


Measure an AI agent: the first month
byBruno Galo · Published on 16 Nov 2025
Last updated 27 Oct 2026
Ask what an agent's automation rate is and you will usually get a confident number. Ask what happened to total process cost, error rate or cycle time and the answer is much less confident, and frequently unavailable — because nobody measured the process before the agent arrived.
This is the central measurement problem with agent deployments. The metrics that are easy to produce are the ones the agent generates about itself: how many items it processed, what proportion it handled without human involvement, its average confidence. These are inputs, not outcomes. An agent can report a high automation rate while total process cost is unchanged, because the work moved into an escalation queue that nobody counts.
The metrics that matter are the ones about the process, not the agent. They are harder to collect, require a baseline captured before deployment, and are the only basis on which anyone can honestly say whether the thing worked.
What should I measure in the first month of an AI agent?
In the first month, measure whether the agent is right and whether the work it hands back gets done, not whether it saved money. Track five things: error rate on a sample of automated actions, escalation precision, escalation queue depth and ageing, reversal rate, and volume against your pre-launch baseline. Leave automation rate and ROI claims for later.
- Error rate on sampled automated actions. Review a fixed sample of what the agent did on its own every week, weighted by consequence. Escalations get reviewed anyway; automated actions do not.
- Escalation precision. The share of escalations that were genuine problems. Low precision burns reviewer attention.
- Escalation queue depth and ageing. Is the work the agent hands back being done, and how old is the oldest item? The design of that queue is covered in the post on agent handoffs.
- Reversal rate. How often a human undoes or corrects an agent action after the fact. Google Cloud calls this the implicit rejection rate, and it is the most honest early signal, because people rarely give explicit feedback but they do revert.
- Volume and mix against the baseline. Is the agent seeing the cases you designed it for? If there is no baseline, start capturing one now.
An optional sixth line is time to verify, the gap between the agent finishing and a human approving. Google Cloud's point is that if review takes longer than doing the task by hand, the friction outweighs the value.
These are early signals, not conclusions. Quality and handoff metrics still need four to six weeks to mean anything, as the FAQ below says.
A first-month measurement plan
| Week | Focus | What to look at | Decision it supports |
|---|---|---|---|
| Before go-live | Baseline | Cycle time, cost per transaction, error rate and volume for at least one full period | Whether any later claim is provable |
| Week 1 | Is it running safely? | Volume, failures and exceptions, a sample of every automated action type | Stop or continue; obvious threshold errors |
| Week 2 | Is it right? | Sampled error rate by consequence, reversal rate, escalation precision | Tighten or loosen thresholds |
| Week 3 | Is the handed-back work done? | Queue depth, ageing, time to resolution, time to verify | Staffing and ownership of the queue |
| Week 4 | First review | All of the above against week 1; recurring exception types | What to fix in month two; whether process-cost tracking is ready |
The "Agent quality" and "Handoff health" rows of the metric layers table further down hold the full definitions. This plan only puts them in order.
What can wait until later
- Automation rate and average confidence. The lowest priority in month one. They are easy to produce and easy to inflate by loosening thresholds or narrowing scope, as argued in "What works, and what to be honest about" below. Auto-clear rate is a similar trap in invoice reconciliation.
- Process outcomes. End-to-end cycle time and total cost per transaction need one to two quarters.
- Business outcomes. Days to payment and days to close need two to three quarters and careful attribution.
Warning signs in the first month
- The queue grows faster than it is cleared.
- The reversal rate rises week on week.
- Escalation precision falls, which is usually the point where reviewers start rubber-stamping.
- Automation rate rises while the sampled error rate rises too.
For one worked example of a first-month review, the master data agent shows what a sampled check looks like on real records.
Launching an agent and want the measurement in place from day one? Start with our one-day AI readiness assessment.
Why this matters
Measurement determines three outcomes that all arrive later than the deployment.
Whether the agent survives its first bad month. Every agent has one. If the only available evidence is an automation rate, a single visible failure dominates the conversation. If you can show cycle time down, error rate down and cost per transaction down over two quarters, one incident is contextualised rather than decisive.
Whether it improves. Improvement requires knowing which cases fail and why. A deployment measuring only aggregate automation rate has no mechanism for improvement, because the number does not decompose into anything actionable.
Whether the next one gets funded. Agent programmes are usually sequential — one process, then another. The second is funded on the evidence from the first, and "we automated 85% of matching" is a weaker case to a finance committee than a demonstrated change in cost per transaction and cycle time.
There is a converse risk worth naming. Bad measurement can also make a genuinely poor deployment look successful for long enough to be extended, which is more expensive than an honest early failure.
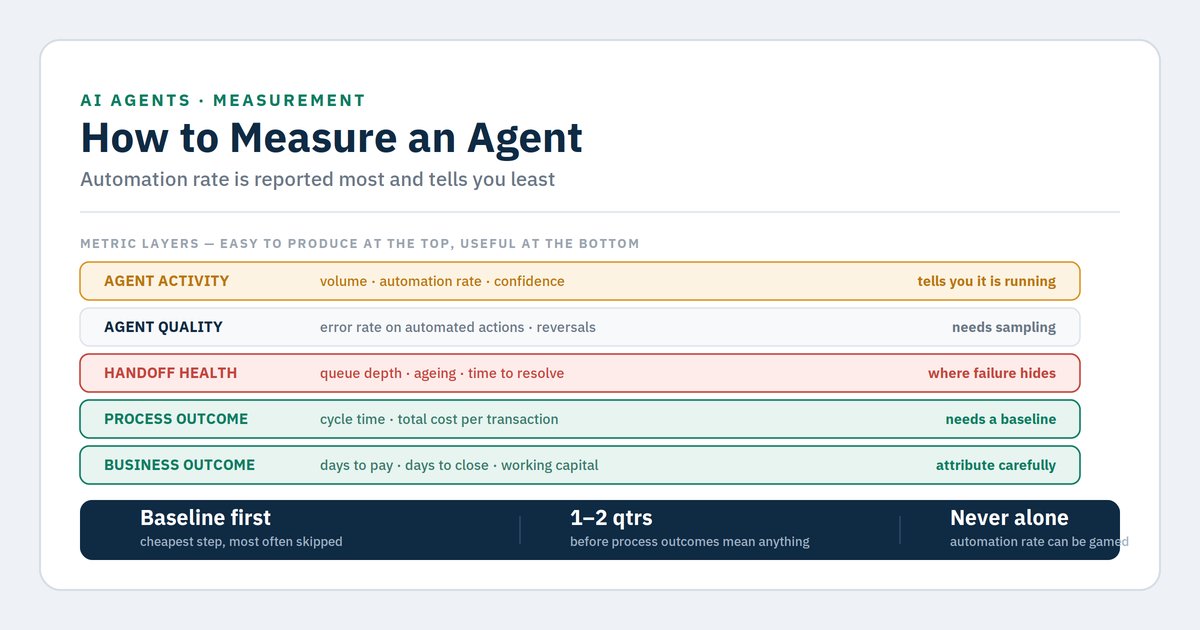
At a glance: the metric layers
| Layer | Metric | What it tells you | Trap |
|---|---|---|---|
| Agent activity | Volume processed, automation rate, average confidence | Whether the agent is running | Says nothing about whether the process improved |
| Agent quality | Error rate on automated actions, reversal rate, escalation precision | Whether autonomous decisions are correct | Requires sampling automated actions, not just reviewing escalations |
| Handoff health | Queue depth, ageing, time to resolution, proportion resolved within target | Whether relocated work is being done | Almost never instrumented at launch |
| Process outcome | End-to-end cycle time, total cost per transaction, error rate reaching customers or the ledger | Whether the deployment worked | Needs a pre-deployment baseline |
| Business outcome | Days to payment, days to close, order accuracy, working capital released | Whether it mattered | Slow-moving and multi-causal — attribute carefully |
| Learning | Proportion of escalations that could have been rules, threshold changes made, recurring exception types | Whether it will keep improving | Requires a monthly review nobody schedules |
The layer most often missing entirely is handoff health, which is precisely where a failing deployment hides. An agent with a high automation rate and a growing, ageing escalation queue has not reduced work — it has concentrated the difficult work in one place and stopped counting it.
What works, and what to be honest about
What works:
A baseline captured before anything is built. Cycle time, cost per transaction, error rate and volume for at least one full period, ideally two. This is the cheapest and most frequently skipped activity in the entire deployment, and without it every subsequent claim is an assertion.
Total cost of the process, including escalations. The honest denominator is all human time spent on the process — agent supervision, escalation resolution, monitoring, and the periodic tuning. Deployments that count only the automated portion report savings that do not appear in anyone's budget.
Sampled review of automated actions, permanently. Escalations get reviewed because they demand attention. Automated actions do not, which is exactly why errors there are found late. A small permanent sample is the only way to detect quiet degradation.
Error rate split by consequence, not just by count. Ten misclassified low-value items and one wrongly redirected supplier payment are not comparable. Weight by impact or the metric will mislead.
Escalation precision as a first-class metric. The proportion of escalations that turned out to be genuine problems. Low precision means humans are reviewing non-problems, which destroys queue attention and is invisible in every other metric.
What to be honest about:
Without a baseline, you cannot prove the value, and you probably will not get one retrospectively. Reconstructing pre-deployment cycle time from memory produces a number shaped by whoever wants the deployment to have succeeded. Accept that some benefits will be unprovable and be candid about which.
Business outcomes are multi-causal. Days to payment improved — but you also changed terms, added a customer segment and lost a slow payer. Claiming the whole improvement for the agent is the fastest way to lose credibility with a CFO. Attribute conservatively and say what else changed.
Some benefit is real and unmeasurable. Consistency, auditability, resilience to staff absence, and the removal of work people found demoralising. These matter and they do not appear in a cost metric. State them as qualitative rather than converting them into invented numbers.
Automation rate can be gamed without anyone intending to. Loosening thresholds raises it. Narrowing scope to easy cases raises it. Neither improves the process. If it is reported at all, report it alongside error rate and escalation precision so it cannot move alone.
Measurement has a cost. Instrumenting everything on this list is disproportionate for a small deployment. Pick the layers that match the stakes — agent quality, handoff health and one process outcome is a defensible minimum.
Decision framework: building the measurement
Run in order. Stop at the first match.
1. Do you have a pre-deployment baseline?
If the agent is not live yet, capture one now — one or two full periods of cycle time, cost, volume and error rate. If it is already live, reconstruct what you can, label it as an estimate, and start measuring properly from today rather than arguing about the past.
2. Are you measuring anything beyond agent activity?
If automation rate and volume are all you have, add error rate on automated actions and escalation queue depth. Those two turn a dashboard that cannot fail into one that can.
3. Is handoff health instrumented?
If not, this is the priority: queue depth, ageing, time to resolution, proportion within target. This is where a failing deployment becomes visible first.
4. Are you sampling automated actions for correctness?
If not, start a small permanent sample. Reviewing only escalations means you are checking the cases the agent already knew it was unsure about.
5. Can you state total process cost including all human time?
If not, build that number. It is the one a finance committee will ask for and the one that determines whether the next deployment is funded.
6. Do you have a monthly review categorising escalation resolutions?
If not, schedule it with a named owner. Without it the agent's performance is static from launch.
7. All of the above and the numbers look good but nobody believes them?
The issue is transparency rather than measurement. Publish the method, the caveats and what you cannot attribute. Confidence in a number comes from stated limitations more than from its size.
Indicative cost and effort
| Workstream | Typical elapsed time | Effort profile |
|---|---|---|
| Pre-deployment baseline capture | 4–8 weeks elapsed | Light effort, long elapsed — must span full periods |
| Agent activity and quality instrumentation | 2–3 weeks | Light — mostly available from the agent |
| Handoff health instrumentation | 2–4 weeks | Medium — usually requires build |
| Process cost model including escalations | 2–3 weeks | Medium — analysis, needs honest time capture |
| Sampled review process design | 1–2 weeks | Light, then ongoing |
| Reporting and dashboard | 2–4 weeks | Medium |
| Monthly learning review | 1 week setup, ongoing | Light but must be sustained |
Assumes one agent on one process with data available in the ERP or integration platform. Get a quote for a scoped estimate.
How companies measure AI agent maturity
There is no single agreed scale, so treat this as a working ladder rather than a standard. It measures maturity by what the team can prove, in four steps that follow the timeline in this post.
- Running (month one). Activity, sampled quality and handoff health. The agent works and the handed-back work is visible.
- Trusted (months two to three). Error and reversal rates are stable, escalation precision is high enough that reviewers act on alerts, and the monthly learning review actually happens.
- Proven (quarter two). Process outcome against the baseline: cycle time and total cost per transaction, including the time spent on escalations.
- Compounding (quarter three onwards). Business outcomes attributed conservatively, escalations converted into rules, and the next agent funded on evidence.
A deployment moves up a step only when the evidence for the previous one exists. Claiming cost savings in month one is how a sound agent ends up with an unsound reputation.
FAQ
What should I measure in the first month of an AI agent?
Error rate on a sample of automated actions, escalation precision, escalation queue depth and ageing, reversal rate, and volume against a baseline. Together they show whether the agent is right and whether the work it hands back gets done. Cost and ROI need longer, so keep them out of the month-one report.
What single metric should we report to the board?
Cost per transaction and cycle time, with error rate alongside so efficiency cannot be shown without quality. If only one, cycle time — it is harder to game and correlates with most of the benefits people actually care about.
How long before the numbers mean anything?
Agent quality and handoff health become meaningful within four to six weeks. Process outcomes need one to two quarters. Business outcomes — days to payment, days to close — typically two to three quarters, because they are slow-moving and need a clean period after the deployment settles. For what to watch before then, see the first-month plan near the top of this post.
What should be the lowest priority when measuring an agent?
Automation rate and the agent's own confidence scores. They are the easiest numbers to produce and to inflate, and they say nothing about whether the process improved. If they are reported at all, report them only next to error rate and escalation precision.
Should we measure against a target or against the baseline?
Against the baseline, primarily. Targets set before deployment are guesses, and missing an arbitrary target on a deployment that materially improved the process produces the wrong conversation.
What if the agent is working but the numbers have not moved?
The usual causes are that the automated portion was not the constraint, the work moved into an uncounted escalation queue, or an upstream problem dominates. All three are findings worth having, and all three are invisible if you only measure automation rate.
How do companies measure AI agent maturity?
By what they can prove. First that the agent runs safely, then that its decisions are right and the handed-back work gets done, then a process improvement against a baseline, and finally business outcomes attributed conservatively. Each step needs the evidence of the one before it.
Do we need a separate analytics tool?
Usually not at mid-market scale. Most of these metrics can be derived from the ERP and the integration platform's own logs. The gap is normally the process cost model and the sampled review, and neither of those is a tooling problem.
How quickly can we get the underlying data connected well enough to measure this?
Quicker than most teams assume for the plumbing. With a real-time sync platform such as Stacksync (we are an implementation partner), the data feeding an agent's metrics can be live within weeks. The slower part is agreeing which of the metrics above actually matter for your agent before you start measuring, so you are not just producing clean numbers on the wrong things.
Closing — Next steps
The agent metric that gets reported is almost always the one the agent produces about itself, and it is the one least connected to whether the deployment was worth doing. The useful measures sit at the process level, they need a baseline, and they include the work the agent handed back.
If an agent is already running and you want to know where you stand: pull the escalation queue depth and its ageing profile, then pull total human hours spent on the process this month. Those two numbers, against whatever you know of the pre-deployment state, will tell you more than any automation rate.
If you are about to launch an agent, or launched one recently without a baseline, the one-day AI readiness assessment is where we would start.
About the author
Bruno Galo is the founder of Atypical Tech, a NetSuite consultancy serving mid-market clients across Iberia. He specializes in connecting CRM and ERP systems for seamless order-to-cash workflows, building automated order management pipelines that eliminate manual data entry between sales and finance teams. As an official Stacksync implementation partner, Bruno designs and deploys AI agents on integration platforms to handle exception routing, document processing, and reconciliation — turning fragmented order flows into reliable, self-monitoring systems.
LinkedIn: https://www.linkedin.com/in/brunogd
Sources
- APQC, Open Standards Benchmarking — process cost and cycle time measures — https://www.apqc.org
- NIST, AI Risk Management Framework — measurement and monitoring of AI systems — https://www.nist.gov/itl/ai-risk-management-framework
- Google Cloud, The KPIs that actually matter for production AI agents (26 Feb 2026), implicit rejection rate, time to verify and cost per successful task — https://cloud.google.com/transform/the-kpis-that-actually-matter-for-production-ai-agents
- Oracle NetSuite, reporting and saved search documentation — https://docs.oracle.com/en/cloud/saas/netsuite/
- COSO, Internal Control — Integrated Framework — monitoring activities — https://www.coso.org
- Atypical Tech engagement experience, mid-market agent deployments across Iberia
Comments
No comments yet.
Leave a comment
Your comment will be reviewed before publishing.
Controller: Atypical Tech S.L. Purpose: to answer your enquiry. Legal basis: your consent. Rights: access, rectification, erasure and the others described in the policy, by writing to hello@atypicaltech.com.